The talk
Todd walks through the deck.
Sources
Every number in the deck links to where it came from. Speeds were measured by the people credited below unless a slide says projected, and where a figure is the vendor's or the author's own, we say so. Quality scores are for the full-precision models; the deck runs 4- and 8-bit versions. Checked October 21, 2026.
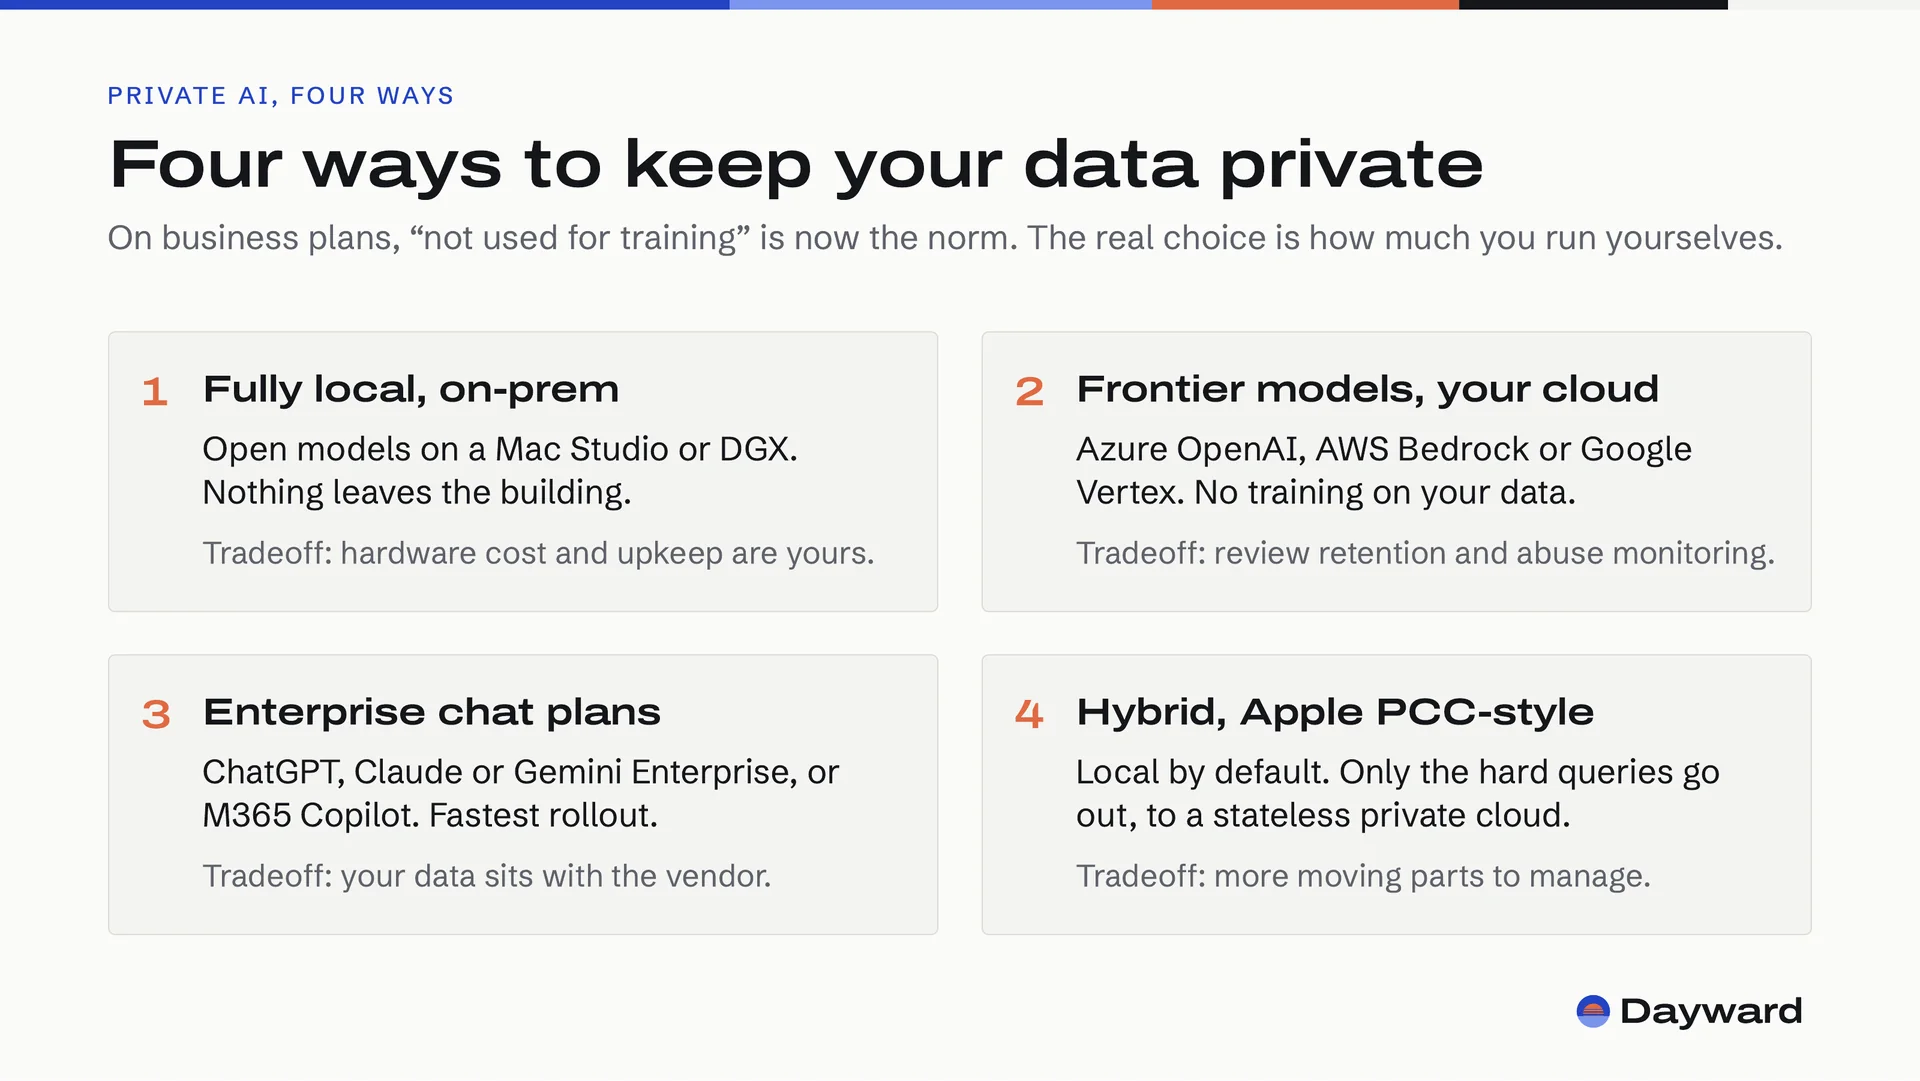
1Four ways to keep your data private
- Microsoft: Azure OpenAI data privacy
- AWS: Amazon Bedrock data protection
- Google Cloud: Vertex AI generative AI data governance
- OpenAI: enterprise privacy (ChatGPT Enterprise)
- Anthropic: is my data used for model training?
- Google Cloud: Gemini data governance
- Microsoft: Microsoft 365 Copilot privacy
- Apple Security Research: Private Cloud Compute
- NVIDIA: DGX Spark
2From your pocket to the server closet
Segue slide; no claims or numbers. It introduces the device tour: iPhone, MacBook, Mac mini, Mac Studio, cluster.
3iPhone & iPad
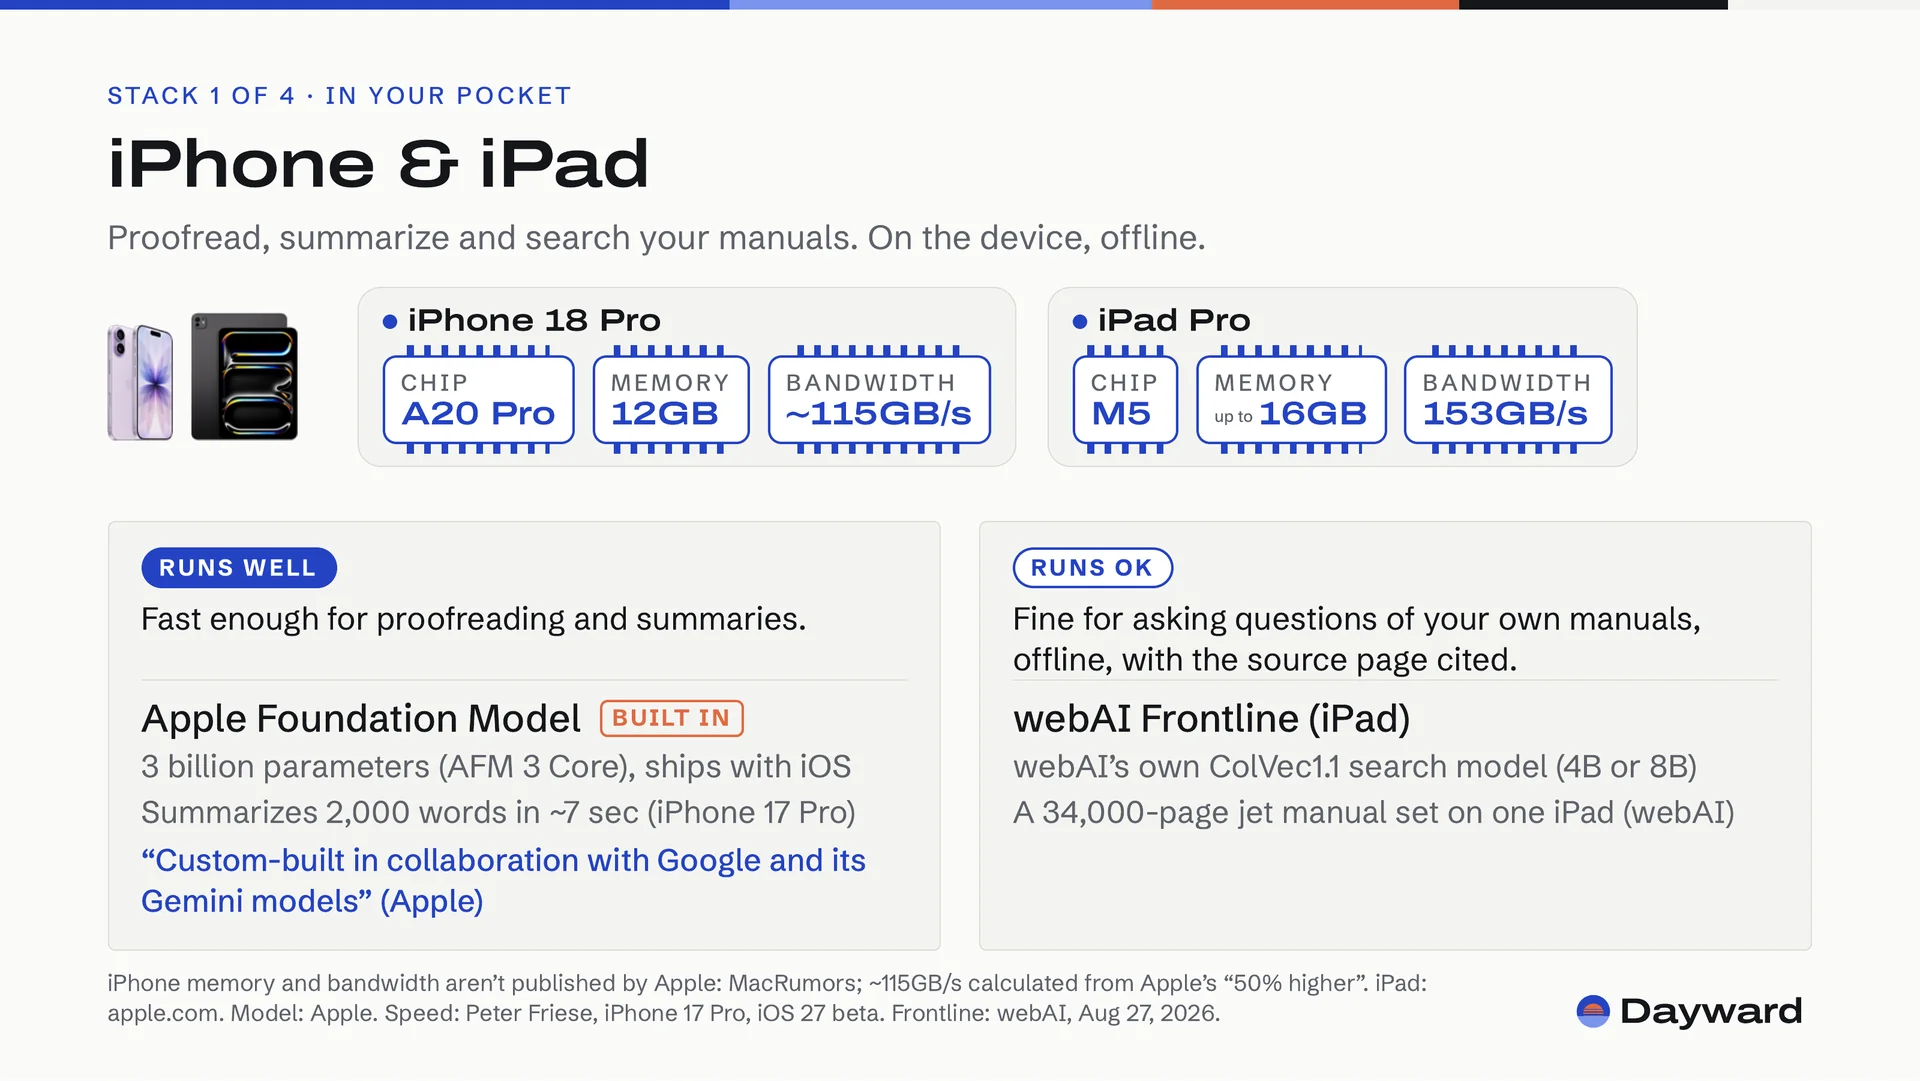
- Apple: iPhone 18 Pro tech specs (A20 Pro)
- Apple: iPhone 18 Pro (“50% higher memory bandwidth”)
- MacRumors: iPhone 18 Pro and Pro Max have 12GB RAM
- MacRumors: A19 Pro memory bandwidth (76.8GB/s)~115GB/s = 76.8 × 1.5, calculated
- Apple: iPad Pro tech specs
- Apple ML Research: third-generation Apple Foundation Models
- Apple Newsroom: Apple Intelligence, June 2026
- Google and Apple joint statement, Jan 12, 2026
- Peter Friese: speech summary timing (iPhone 17 Pro, iOS 27 beta)6.95 s; the author calls it an informal test
- webAI: Frontline press release, Aug 27, 2026
- webAI: under the hood of Frontline (ColVec1.1)
- webAI on X: Frontline launch
4MacBook Air
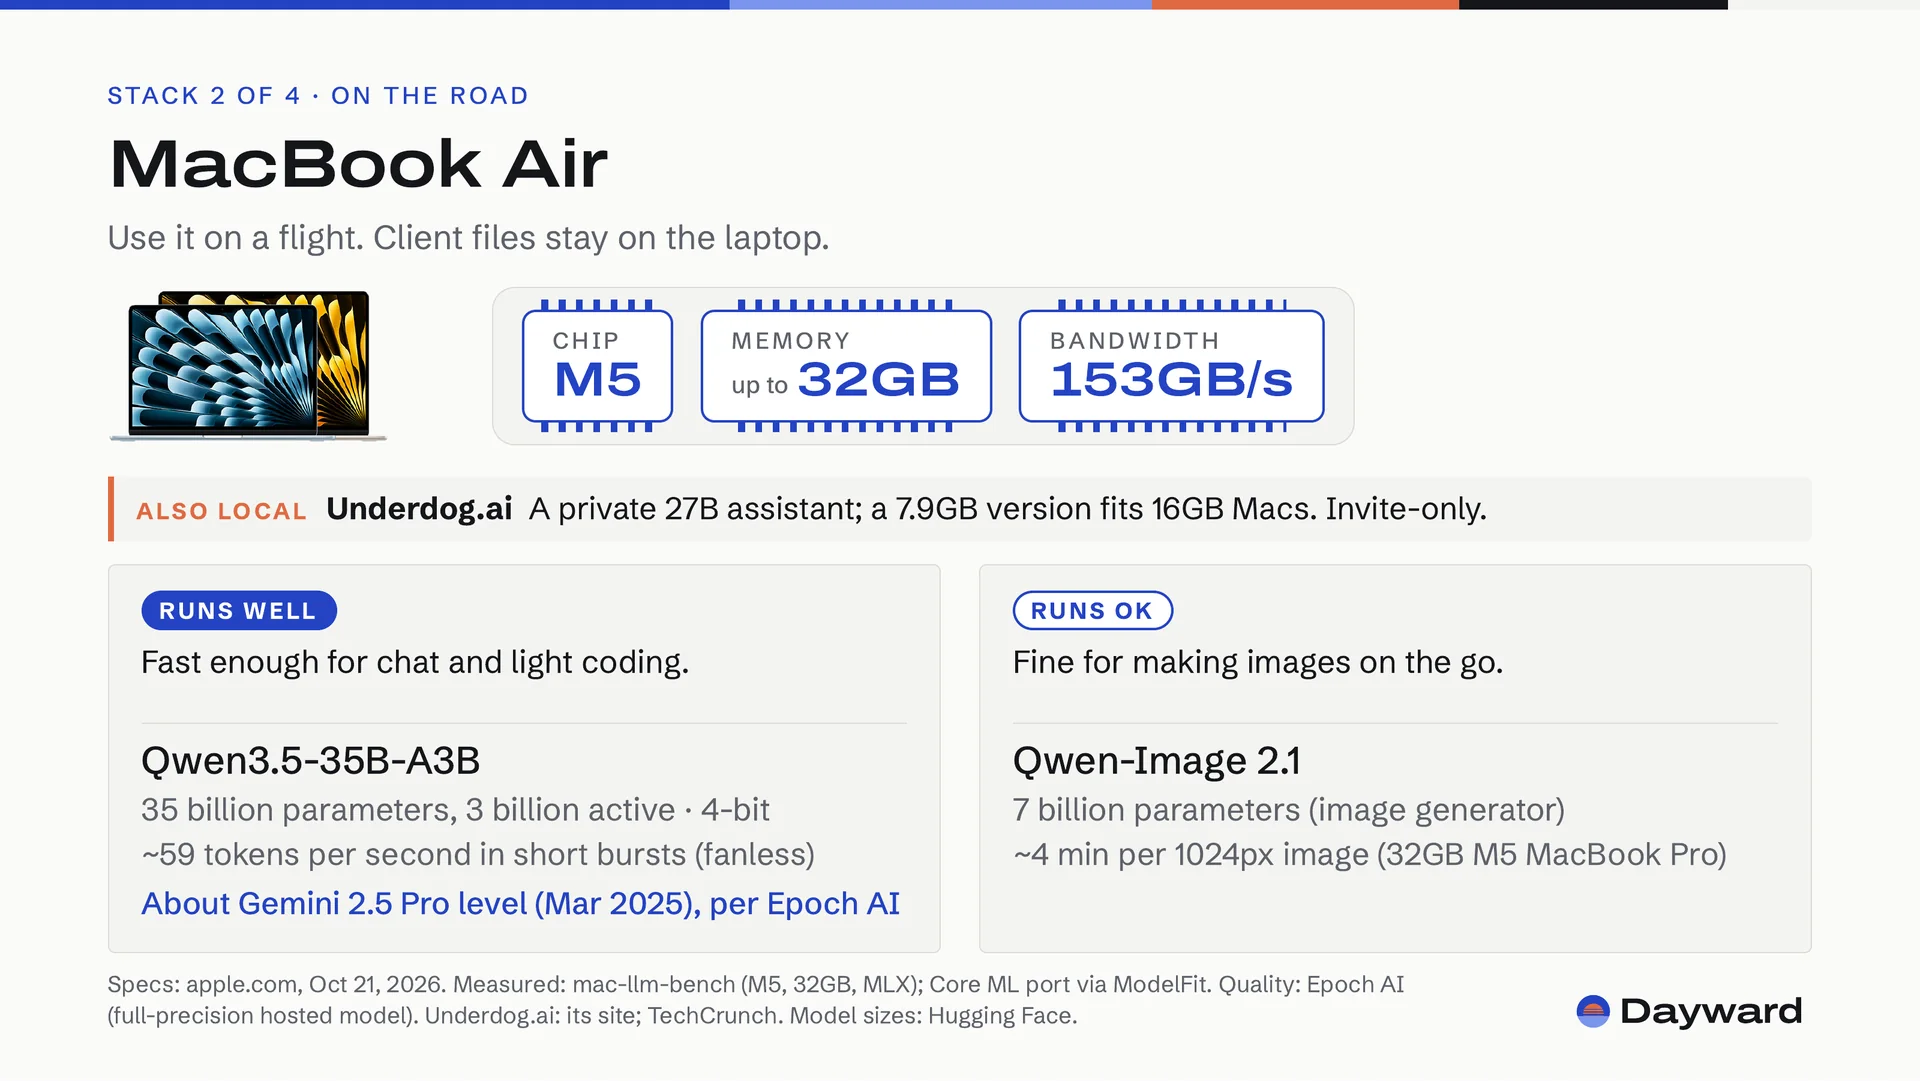
- Apple: MacBook Air tech specs
- MLX (Apple’s machine-learning framework)
- mac-llm-bench (Enes Cingöz): Qwen3.5-35B-A3B on M558.8 tok/s, MLX 4-bit, M5 10-core GPU, 32GB, 4K context, a short 128-token run (the Air is fanless, so sustained speed may drop); the GGUF build ran 31.3
- Epoch AI: open vs closed model capability gap (ECI)Qwen 3.5 Flash (Alibaba’s hosted 35B-A3B; Epoch marks the mapping “likely”) ≈ Gemini 2.5 Pro (Mar 2025)
- ModelFit: Qwen-Image 2.1 on Apple silicon221–250 s per 1024×1024 image, M5 MacBook Pro 32GB, community Core ML port
- Hugging Face: Qwen-Image 2.1 model card
- Underdog.ai7.9GB build fits 16GB Macs (Underdog’s own claim); invite-only on Mac
- TechCrunch: Underdog.ai launch, Oct 6, 2026
- Hugging Face: Qwen3.5-35B-A3B model card
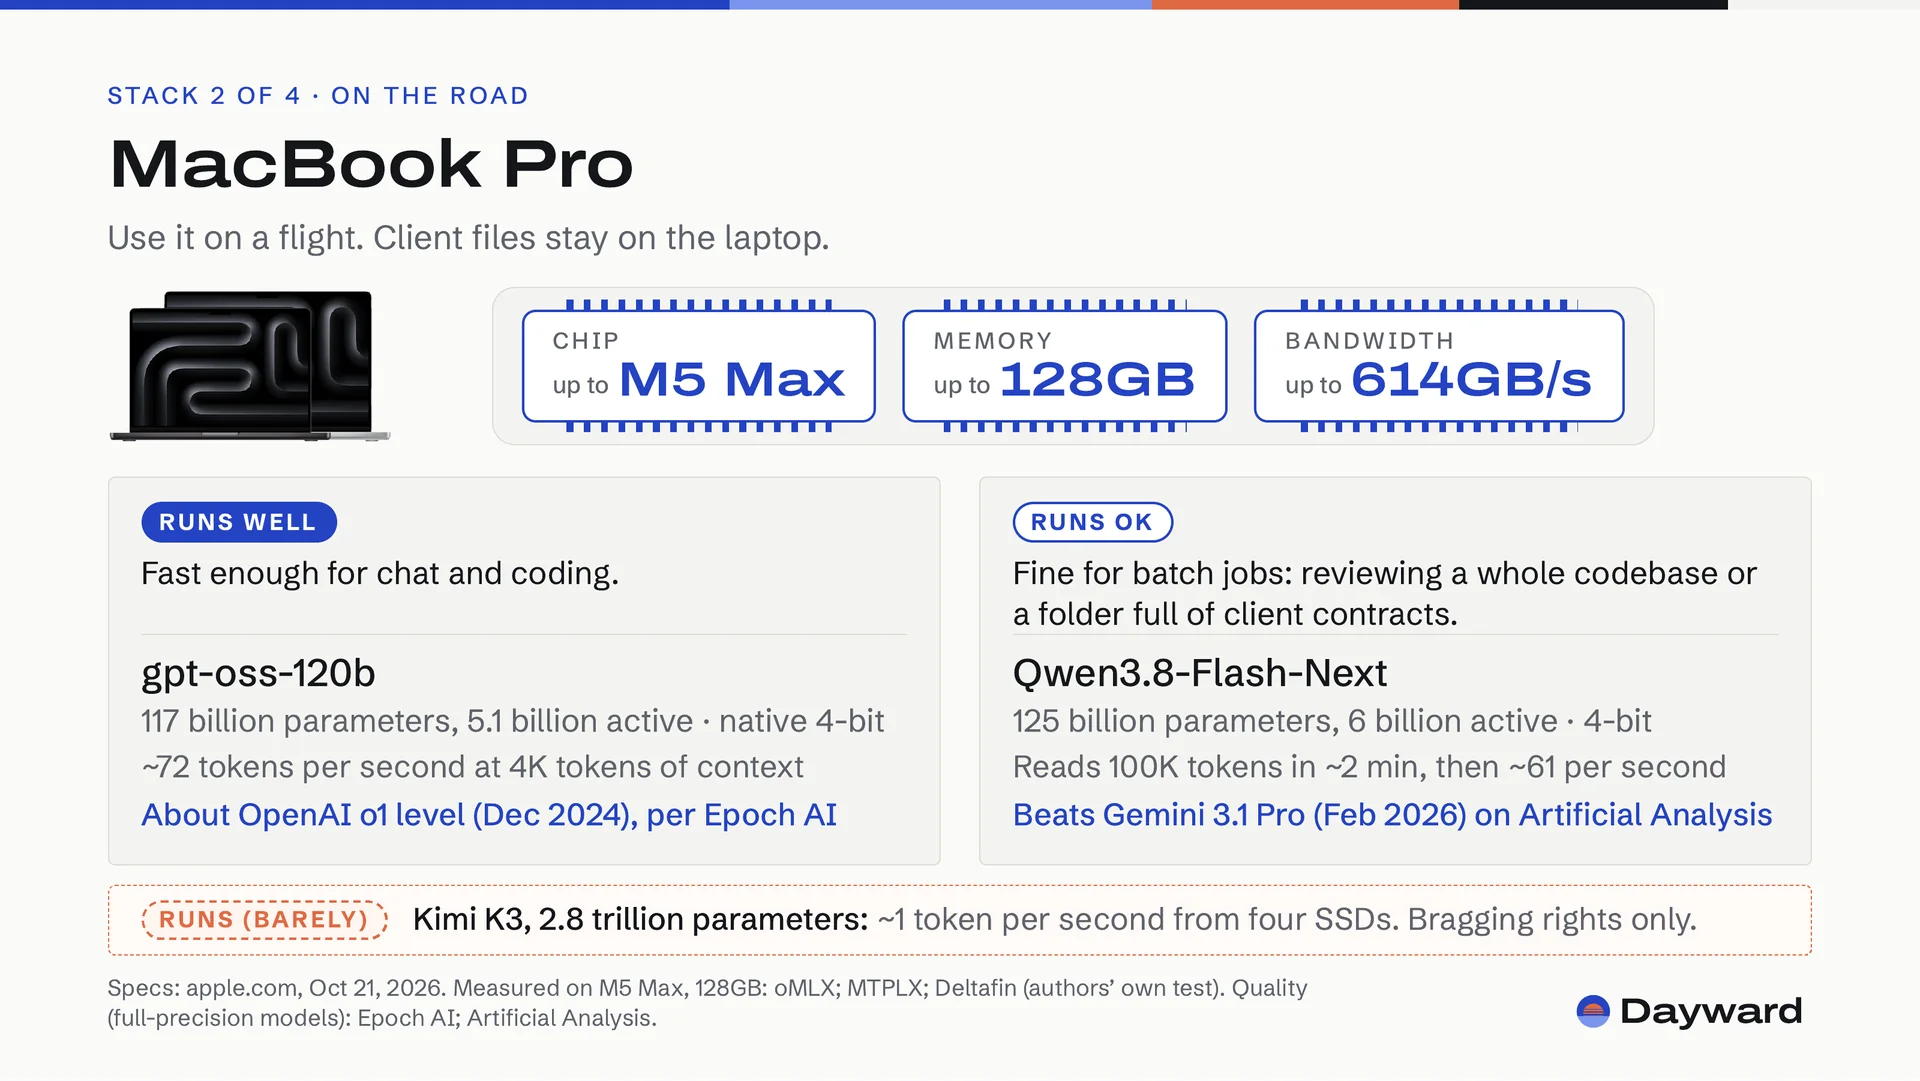
5MacBook Pro
- Apple: MacBook Pro tech specs
- oMLX: gpt-oss-120b on M5 Max 128GB71.5 tok/s at 4K context. oMLX logs the chip, not the Mac model
- Hugging Face: gpt-oss-120b model card
- Epoch AI: open vs closed model capability gap (ECI)gpt-oss-120b ≈ OpenAI o1 (Dec 2024)
- MTPLX benchmarks: Qwen3.8-Flash-Next, 100K context
- MTPLX on GitHub (Youssof Al Toukhi)
- oMLX: Qwen3.8-Flash-Next on M5 Max 128GB
- Hugging Face: Qwen3.8-Flash-Next model card125B parameters plus a 51B n-gram table (180B on disk)
- Artificial Analysis: Intelligence Index leaderboard
- Deltafin (Argonaut Labs fork): Kimi K3 at ~1 token/sec on an M5 Max 128GB MacBook Pro1.00 tok/s with the drafter on, 0.92 off; self-reported by the authors
- Deltafin original engine (gavamedia, MIT)Built by Chris Ringrose (github.com/chrisringrose) and contributors
- Hugging Face: Kimi K3 model card2.78T parameters, 104B active, native MXFP4
- Hacker News discussion of Deltafin
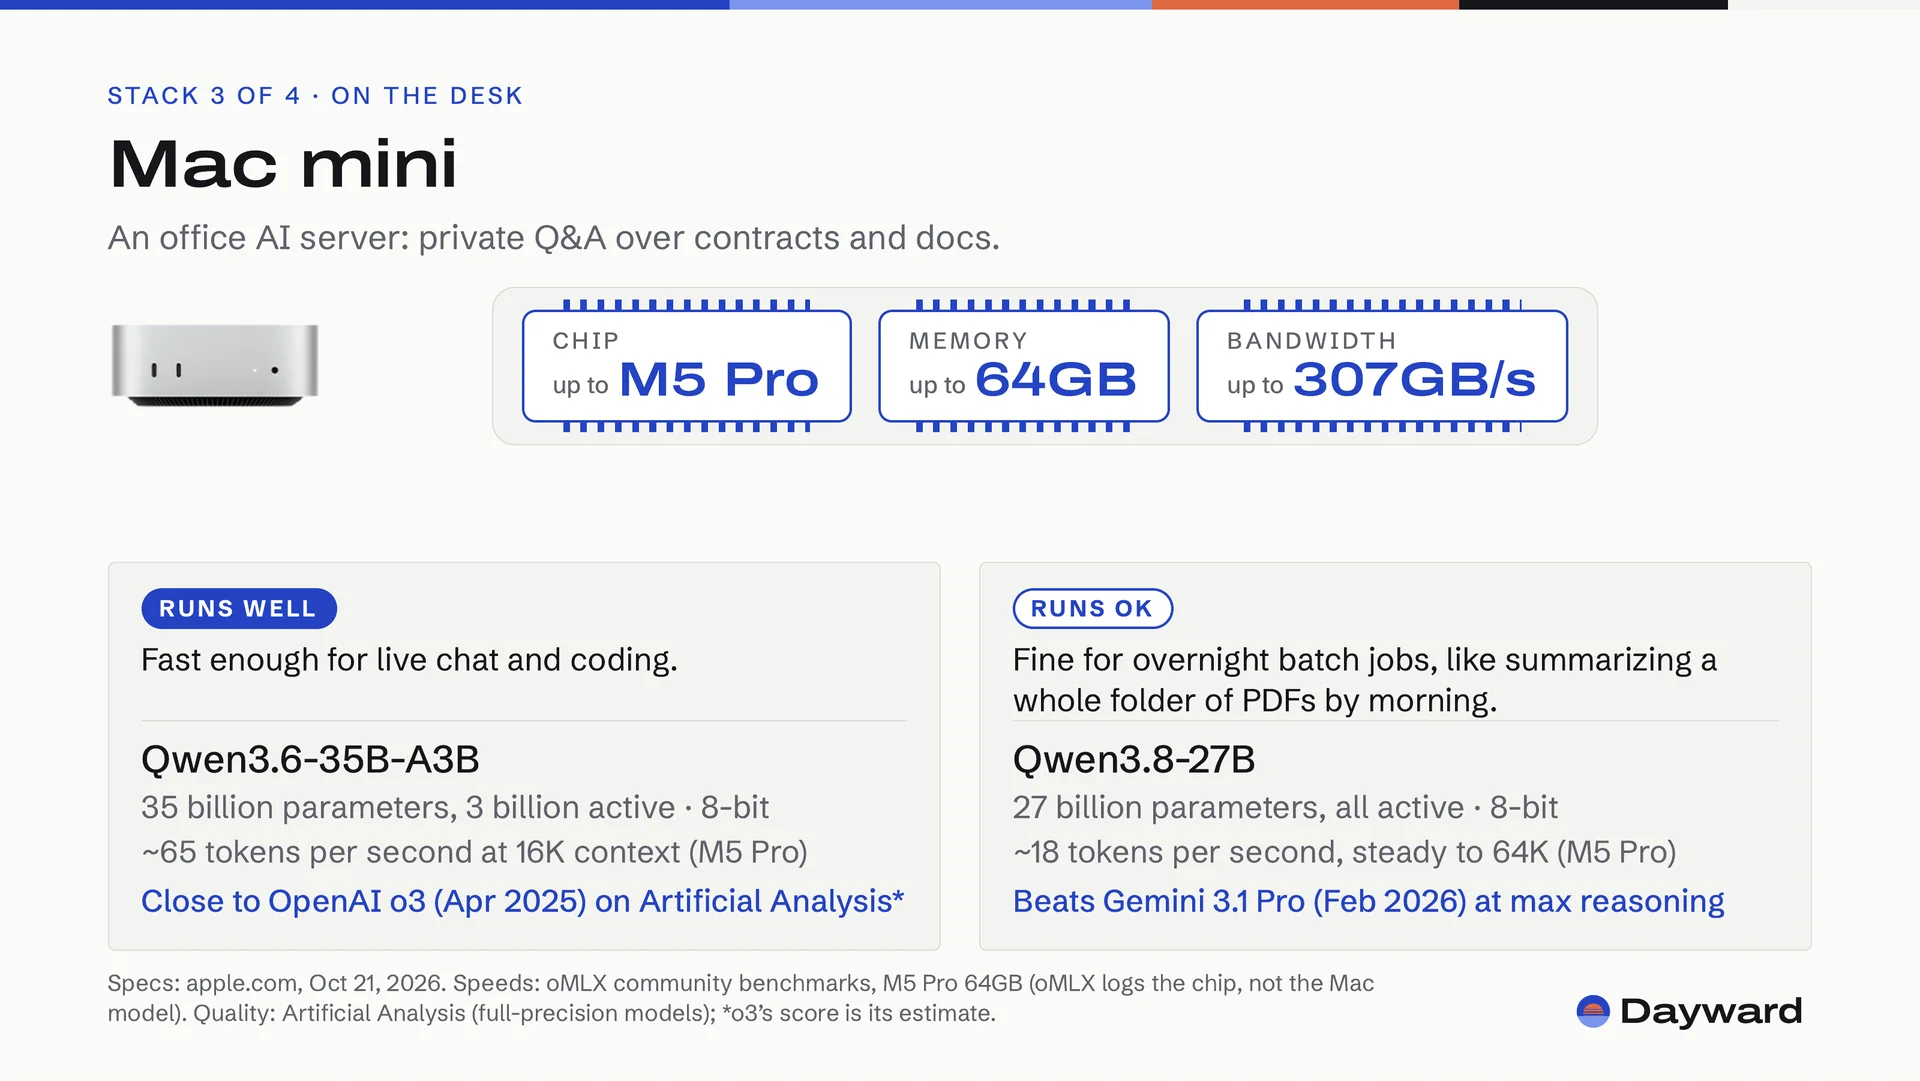
6Mac mini
- Apple: Mac mini tech specs
- oMLX: Qwen3.6-35B-A3B 8-bit on M5 Pro 64GB, 16K context65.5 tok/s. oMLX logs the chip, not the Mac model
- Hugging Face: Qwen3.6-35B-A3B model card
- oMLX: Qwen3.8-27B 8-bit on M5 Pro 64GB, 16K context
- oMLX: Qwen3.8-27B 8-bit on M5 Pro 64GB, 64K context
- Hugging Face: Qwen3.8-27B model card
- Artificial Analysis: Qwen3.8-27BAt max reasoning (xhigh) it scores 34 vs Gemini 3.1 Pro Preview’s 30; at medium 28, at low 26
- Artificial Analysis: Intelligence Index leaderboardQwen3.6-35B-A3B 18 vs OpenAI o3 20*, where o3’s score is an Artificial Analysis estimate
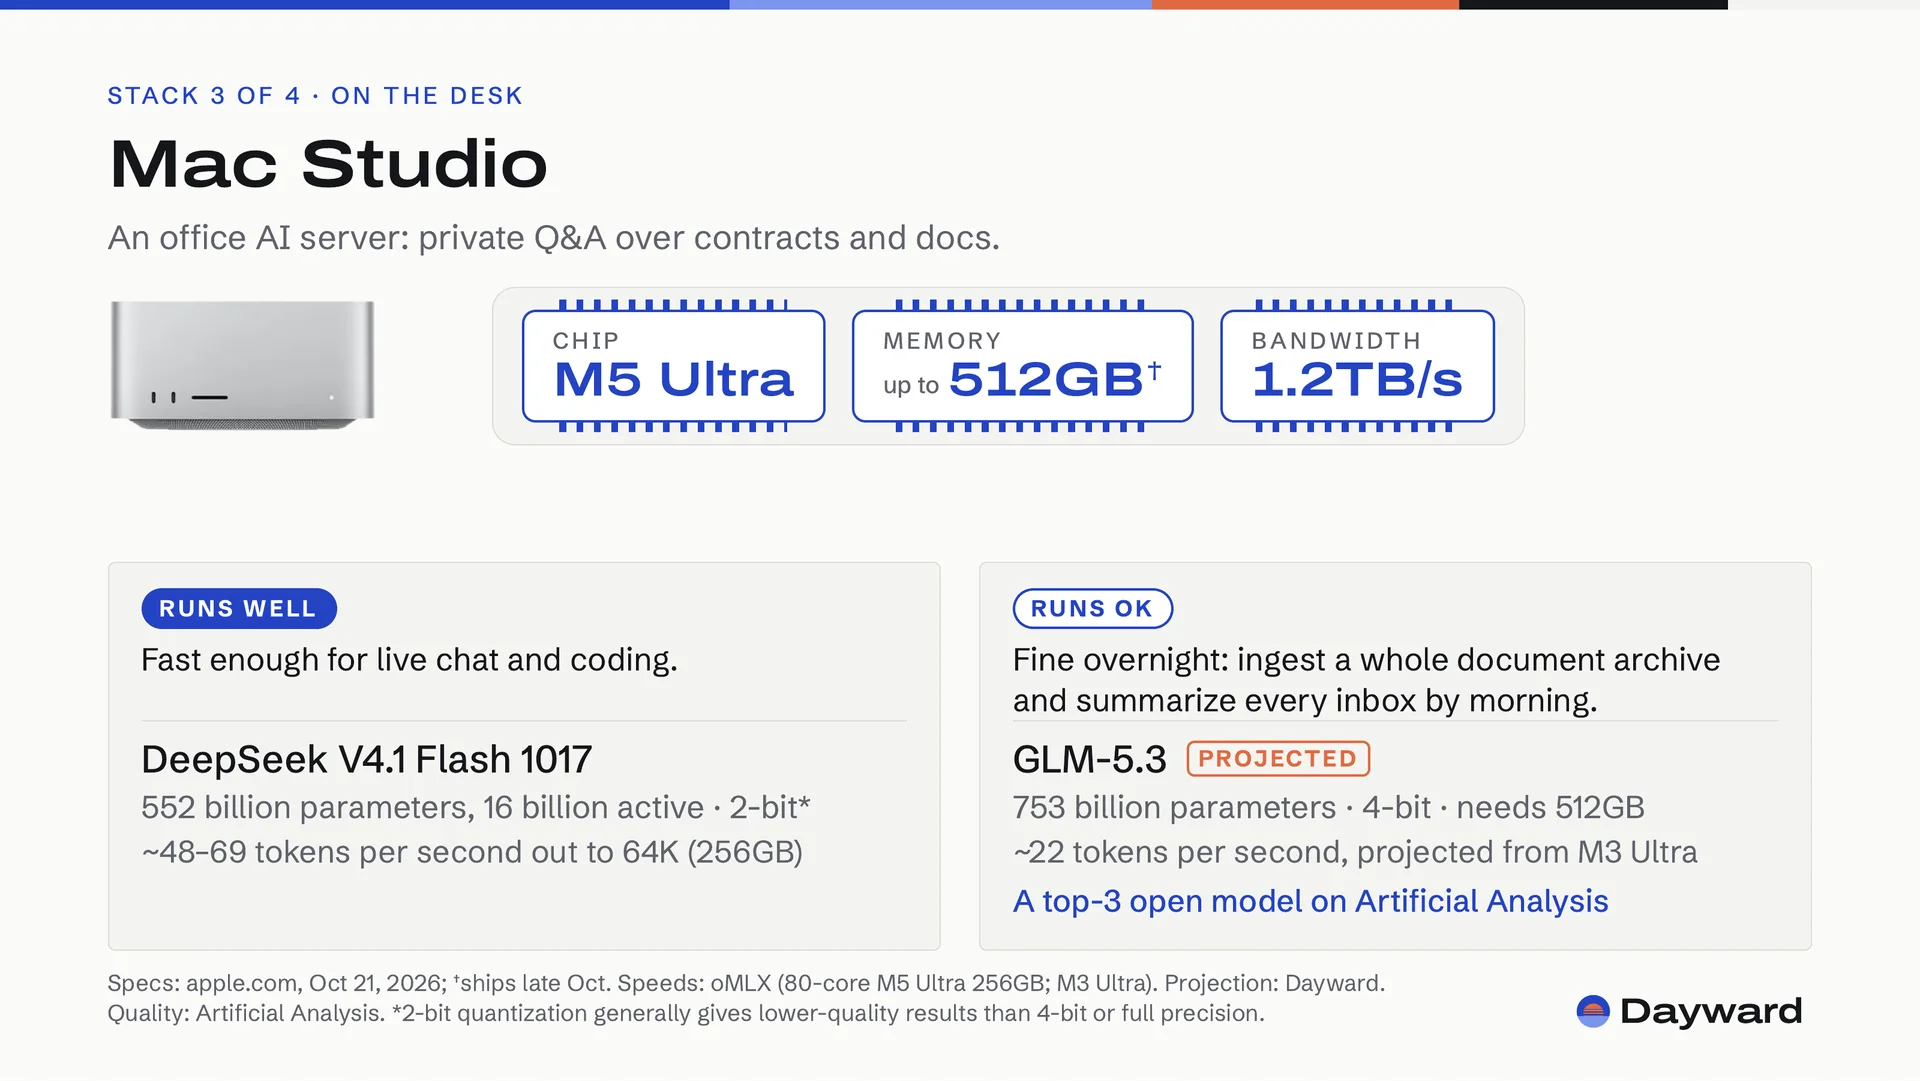
7Mac Studio
- Apple: Mac Studio tech specs
- oMLX: DeepSeek V4.1 Flash 1017, 2-bit mix, on M5 Ultra (80-core) 256GB, 1K context51.4 tok/s, Oct 21, 2026, MTP on
- oMLX: same session, 4K context47.5 tok/s
- oMLX: same session, 16K context69.3 tok/s, peak memory about 179GB
- oMLX: same session, 64K context67.5 tok/s. Apple sells 256GB only with the 80-core GPU, so we used only 80-core results. No 4-bit V4.1 results exist on M5 Ultra yet.
- Hugging Face: DeepSeek-V4.1-Flash-1017 model cardOct 17, 2026, a minor update to V4.1 Flash
- Hugging Face: DeepSeek-V4.1-Flash model card and technical report552B backbone parameters, 16B active per token during decode, plus 196B of Engram lookup memory
- Artificial Analysis: DeepSeek V4.1 Flash 1017Index 45 at max effort, but that score is for the full-precision model. The slide runs a 2-bit mix, so it shows no quality score: 2-bit quantization generally gives lower-quality results than 4-bit or full precision.
- oMLX: GLM-5.3 4-bit on M3 Ultra 512GB (basis for the projection)14.8 tok/s at 4K context. Projected ~22 tok/s on M5 Ultra 512GB = 14.8 × 1.47–1.59
- Apple ML Research: measured M5 Ultra vs M3 Ultra decode speedup, 1.55–1.59×Apple’s own figures
- Context Studios: M5 Ultra vs M3 Ultra (MacStories numbers, @viticci)
- Hugging Face: GLM-5.3 model card
- Artificial Analysis: GLM-5.3
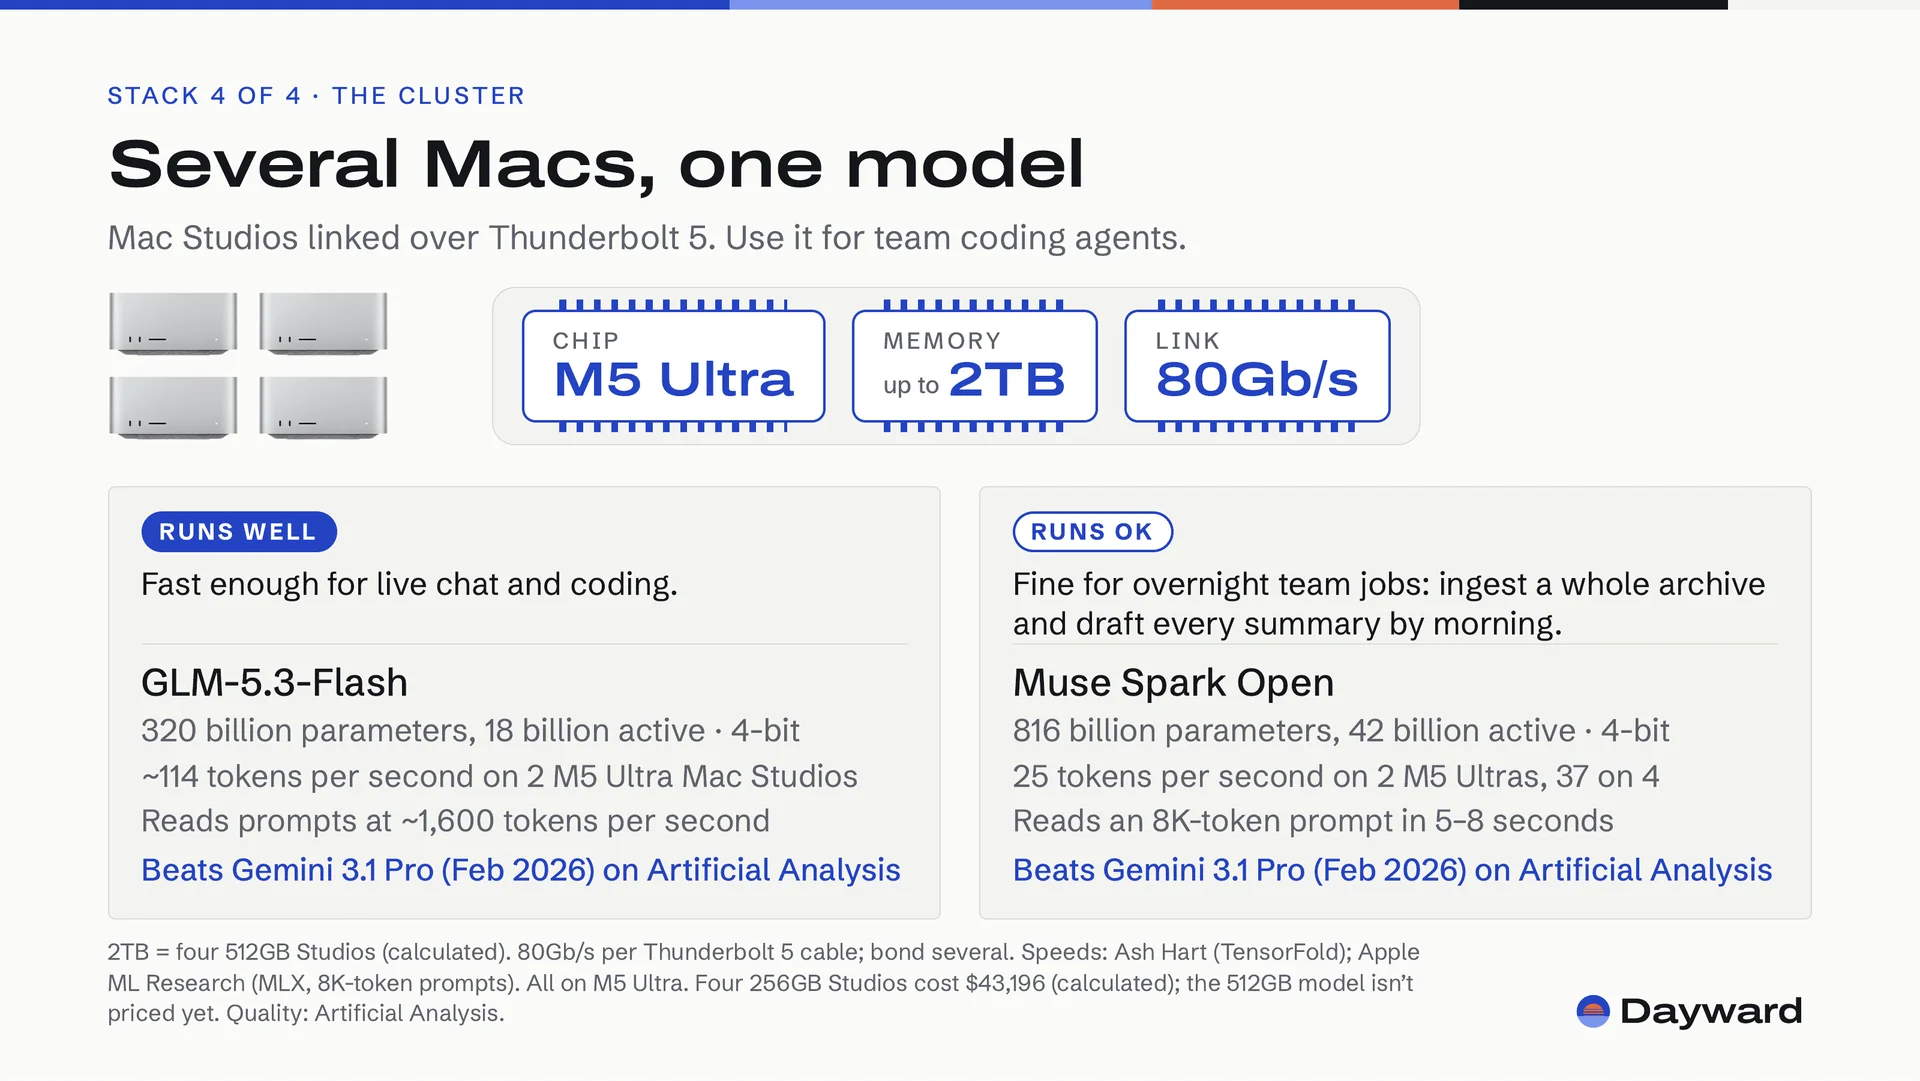
8Several Macs, one model
- Ash Hart: GLM-5.3-Flash on two M5 Ultras, 114 tok/s4-bit, TensorFold (his own software), 4 bonded TB5 cables; reads prompts at ~1,600 tokens per second
- Mia: sharing the run
- Hugging Face: GLM-5.3-Flash model card
- TensorFold (Ash Hart’s inference engine)Code: github.com/ashhart/TensorFold
- Apple ML Research: MLX distributed inference (Muse Spark Open)NVFP4 4-bit, 8K-token context, tensor parallel: 24.99 tokens per second on 2× M5 Ultra, 36.73 on 4×; time to first token 8.2 s on 2×, 4.8 s on 4× (Table 2). Apple’s own figures
- Apple: Mac Studio M5 Ultra (36-core CPU, 80-core GPU) 256GB$10,799 with 1TB; four = $43,196, calculated. The 512GB model isn’t priced yet (Oct 21, 2026)
- Hugging Face: Muse Spark Open model card
- Apple: Mac Studio tech specs (Thunderbolt 5, 80Gb/s)
- Alex Cheema: bonding Thunderbolt 5 cables
- Artificial Analysis: GLM-5.3-Flash vs Gemini 3.1 Pro
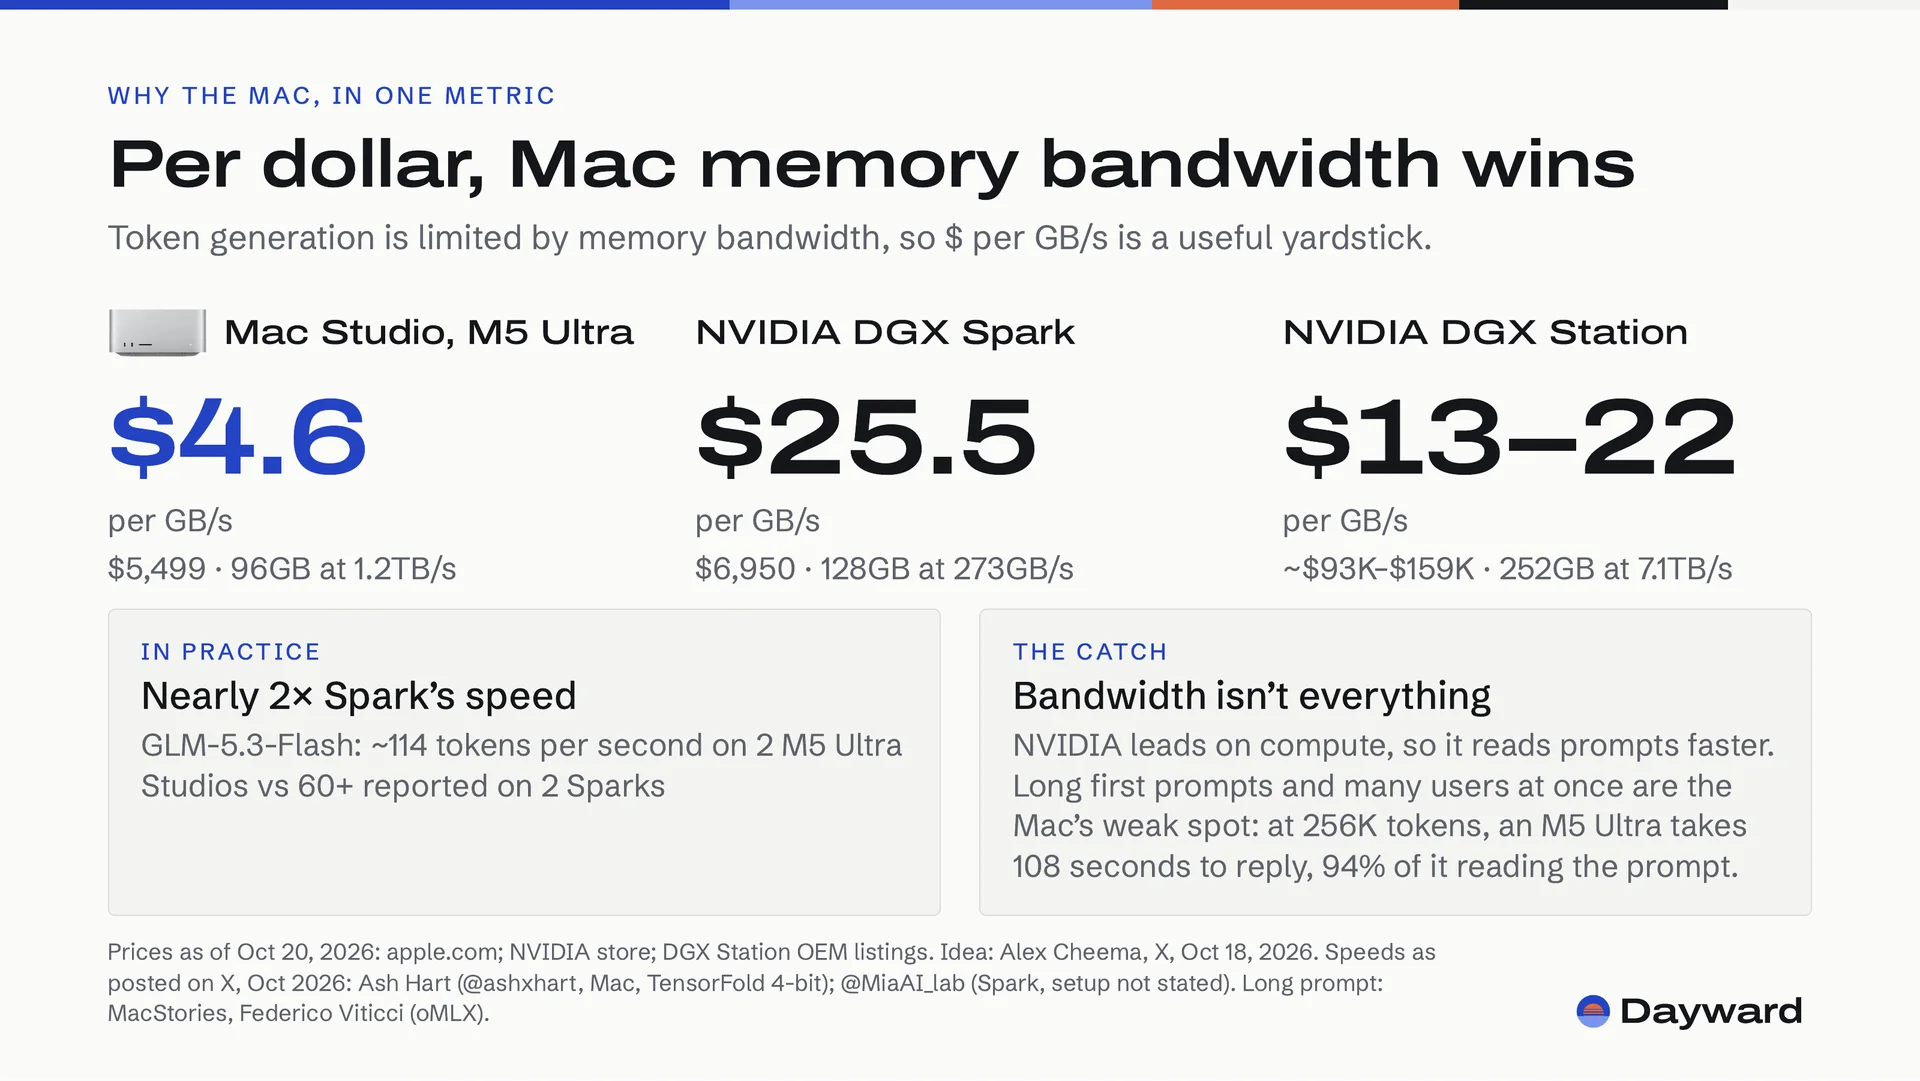
9Why the Mac, in one metric
- Apple: Mac Studio specs and price
- NVIDIA: DGX Spark
- The Register: 128GB DGX Spark now $6,950; new 64GB model $4,999
- Hardware Busters: DGX Spark 64GB at $4,999, 128GB at $6,950
- BetterClaw: DGX Station pricing
- Alex Cheema: $ per GB/s idea
- Ash Hart: two M5 Ultras, 114 tok/s
- Mia: two DGX Sparks, “over 60 tok/s”Oct 3, 2026. Quant and software not stated
- MacStories: M5 Ultra Mac Studio review (Federico Viticci)oMLX, Qwen3.8 Flash-Next 4-bit: a 256K-token prompt takes 108 s, 6.8 s of it writing the answer. Same prompt with a warm cache: 5.8 s
- AiDevCraft: the long-prompt numbers, summarizedSep 22, 2026. Cites the MacStories review
Also checked
- GitButler: local model gauntlet on an M5 Max (Scott Chacon)A real, code-graded test, but small (22 problems). We now quote Epoch AI instead.
- SWE-bench Verified leaderboard (Vals AI)
- Aider polyglot leaderboard
- LiveCodeBench v6 (llm-stats)
- Artificial Analysis: gpt-oss-120b vs Claude Opus 5
- oMLX community benchmarks
- Inco AI: Splash engine benchmarksVendor-measured on a 16-core M5 Pro 48GB with 4-bit models; the Mac mini cards use independent 8-bit results, so we kept those
- Splash 1.4.0 release notes (Qwen3.8-Flash-Next)95 tokens per second at 2-bit (Q2_0) on an M5 Pro 64GB, not the 120 shared on X. Not used
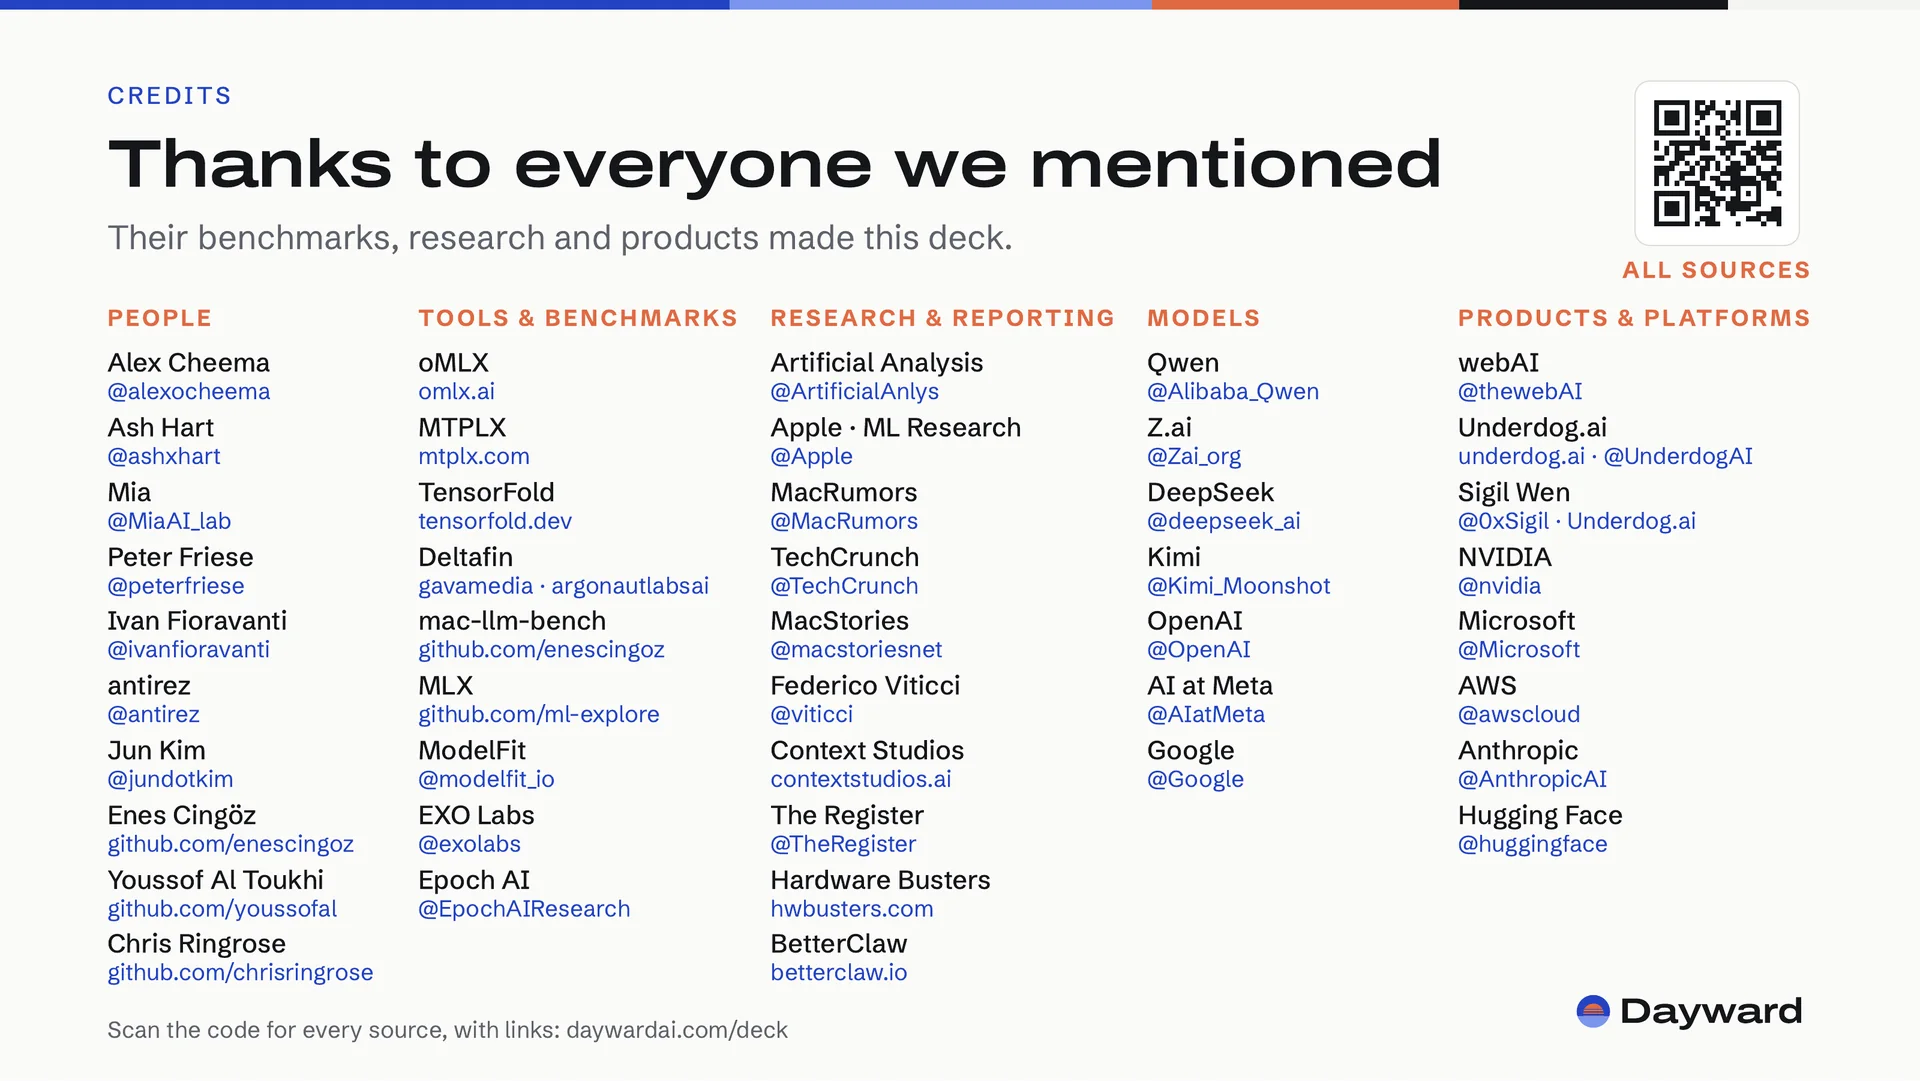
Credits
Thanks to everyone we mentioned. Their benchmarks, research and products made this deck.
People
- Alex Cheema@alexocheema
- Ash Hart@ashxhart
- Mia@MiaAI_lab
- Peter Friese@peterfriese
- Ivan Fioravanti@ivanfioravanti
- antirez@antirez
- Jun Kim (oMLX)@jundotkim
- Enes Cingöz (mac-llm-bench)github.com/enescingoz
- Youssof Al Toukhi (MTPLX)github.com/youssofal
- Chris Ringrose (Deltafin)github.com/chrisringrose
- Sigil Wen (Underdog.ai)@0xSigil
Tools & benchmarks
- oMLX
- MTPLX
- TensorFold
- Deltafingavamedia
argonautlabsai - mac-llm-bench
- MLX (Apple)
- ModelFit@modelfit_io
- EXO Labs@exolabs
- Epoch AI@EpochAIResearch
Research & reporting
- Artificial Analysis@ArtificialAnlys
- Apple, ML Research@Apple
- MacRumors@MacRumors
- TechCrunch@TechCrunch
- MacStories@macstoriesnet
- Federico Viticci (MacStories)@viticci
- Context Studios
- The Register@TheRegister
- Hardware Busters
- BetterClaw
Models
- Qwen@Alibaba_Qwen
- Z.ai@Zai_org
- DeepSeek@deepseek_ai
- Kimi@Kimi_Moonshot
- OpenAI@OpenAI
- AI at Meta@AIatMeta
- Google@Google
Products & platforms
- webAI@thewebAI
- Underdog.ai@UnderdogAI
- NVIDIA@nvidia
- Microsoft@Microsoft
- AWS@awscloud
- Anthropic@AnthropicAI
- Hugging Face@huggingface